Review code you’ve never seen. Show the client the evidence.
A local index of a repository, built on your machine, that hands your coding agent the right code first on day one — the gold file on 40 of 40 public-benchmark queries, where keyword ripgrep opening its top five files whole found 32 of 40, at 31–67× fewer tokens than ripgrep and 51–242× fewer than pasting every source file. On a larger 150-question eval it puts a gold file in the top five on 93.3%, and all 10 misses are published. By default no telemetry and no repository content off your machine, with signed releases and compliance evidence a client’s security review can check. MIT core, free at one seat.
- 01
$pip install neuralmind - 02
$neuralmind build . - 03
$neuralmind install-mcp - 04
$neuralmind install-hooks .
Persistent codebase memory and an MCP server. Works with Claude Code, Codex, Cursor, Cline, Hermes and any MCP client.
Same question, two retrievers
requests@0e322af877
“the exception raised when a request times out”
Gold file: exceptions.py
Tokens into the agent’s window
25,225ripgrep, top five files opened whole
680neuralmind query
exceptions.pynot in ripgrep’s context
- sessions.py
- adapters.py
- api.py
- models.py
- cookies.py
exceptions.pyranked first by neuralmind
- api.py
- models.py
- sessions.py
- adapters.py
- cookies.py
- Gold file found
40 of 40
public-benchmark queries on 4 pinned repos; keyword ripgrep found 32 of 40
Reproducible- Fewer tokens vs ripgrep
31–67×
same queries, against ripgrep opening its top five files whole
Reproducible- Vs pasting every file
51–242×
same queries; the easiest baseline to beat
Reproducible- Top-5 hit rate
93.3%
150 questions on 5 repos; all 10 misses published
Reproducible
Each reruns from a fresh clone with one command. Every number, its source and where NeuralMind loses
Index once. Every session starts oriented.
- 01 / 03
Index
On your machineneuralmind build .parses your repo with tree-sitter into a graph of functions, classes, imports and call edges, and embeds it on your machine. Ten languages plus JavaScript, no config. - 02 / 03
Query
Your agent asks over MCP or a Claude Code hook and gets a project map, the relevant symbols and their callers, deeper only where the question needs it. A local index lookup, not another model call.
L0–L3 disclosure - 03 / 03
Remember
A synapse layer links files you use together and re-ranks recall with those links next session.
Across sessionsneuralmind memory publishwrites them to a file you commit, so teammates start with them.
Quickstart
Six commands. No account, no signup, no hosted service.
- 01
pip install neuralmindPython 3.10+
- 02
cd your-repo && neuralmind build .first build downloads a public embedding model
- 03
neuralmind install-mcpClaude Code; --client cursor | cline | vscode | claude-desktop
- 04
neuralmind install-hooks .Claude Code: session-start memory, prompt-time recall, stale-decision guard
- 05
neuralmind init-hook .rebuild after commits, pulls, checkouts and rebases
- 06
neuralmind benchmark .your own tokens-per-question, on your code
Using Hermes? neuralmind install-hermes-plugin. Other MCP clients point at neuralmind-mcp. CLI reference
$ neuralmind query . "the exception raised when a request times out"
Tokens: 649
…
## Relevant Code Areas
### Cluster 2 (relevance: 4.42)
- Initialize RequestException with `request` and `response` objects. (rationale) — exceptions.py
- The request timed out while trying to connect to the remote server. Requests that produced this error are safe to retry. (rationale) — exceptions.py
- Timeout (code) — exceptions.py
- ConnectTimeout (code) — exceptions.py
- requests.exceptions ~~~~~~~~~~~~~~~~~~~ This module contains the set of Requests' exceptions. (rationale) — exceptions.py
- ReadTimeout (code) — exceptions.py
…
What your agent gets
The right code, in fewer tokens
A map, the relevant symbols and their call edges instead of whole files, deeper only where the question needs it.
- Progressive L0–L3 disclosure
- Project map, relevant clusters, symbol detail, then search.
- Hard context budget
- Set a per-query token budget; NeuralMind trims L3 → L2 → L1 to fit it.
- Read dedup
- In Claude Code, a repeat read of an unchanged file comes back as a short stub; the next read is full again.
- Local retrieval
- A local index lookup, not another model call. TurboVec keeps 4-bit vectors 8–16× smaller than float32, parity gated in CI.
Stays current, and remembers
An index that keeps up with git and says when it hasn’t, plus memory that survives the session.
- Fresh after every git movev4.13.0+
neuralmind init-hook .installs post-commit, post-merge, post-checkout and post-rewrite hooks, so commits, pulls, branch switches and rebases rebuild in the background.- Stale-index warningsv4.17.0+
- When commits since the last build changed the project, or the background rebuild failed, query, search, the MCP tools and the prompt hook say so in one line.
- Learned associations
- A Hebbian synapse layer links files you use together and re-ranks recall with those links;
neuralmind eval . --synapse-abmeasures whether that helps on your repo. - Decisions that go stale with their code
- Architecture decisions are stored with their files. A later commit or pull that changes those files marks them stale, and a hook surfaces a stale one before your agent edits under it.
Local, and verifiable
By default no telemetry and no repository content off your machine, with the evidence a security review asks for.
- Signed, attested releasesv4.14.0+
- cosign-signed images, build-provenance attestations, a CycloneDX SBOM per release and an OpenVEX statement.
- Secret scan
neuralmind scan-for-secrets .reports credentials before they reach the index, a commit or an agent’s context.- CUI profilev4.16.0+
security.profile: cuiturns on the CUI-enclave posture as one setting and refuses what would weaken it.- Data locationsv4.18.0+
neuralmind data-locations .lists every place NeuralMind keeps data for a project, and how to remove each.- SP 800-53 hardening checkv4.19.0+
neuralmind hardeningchecks a project and its host against 17 rules mapped to SP 800-53 controls; audit records forward to syslog as they are written.
Works with your agent
No new IDE, no model swap, no hosted service. Claude Code is tested end to end; other MCP clients connect through the same protocol.
- MCP server
neuralmind install-mcpregisters it with Claude Code, or Cursor, Cline, VS Code and Claude Desktop via--client; any other client points atneuralmind-mcp.- Claude Code hooks
- Memory at session start, related files at each prompt, and a guard that surfaces a stale decision before an edit.
- Hermes plugin
neuralmind install-hermes-pluginruns the same hook actions inside Hermes-Agent.- Ten languages
- Python, TypeScript, Go, Rust, Java, C, C++, C#, Ruby and PHP, plus JavaScript, OpenAPI, SQL DDL and Protocol Buffers.
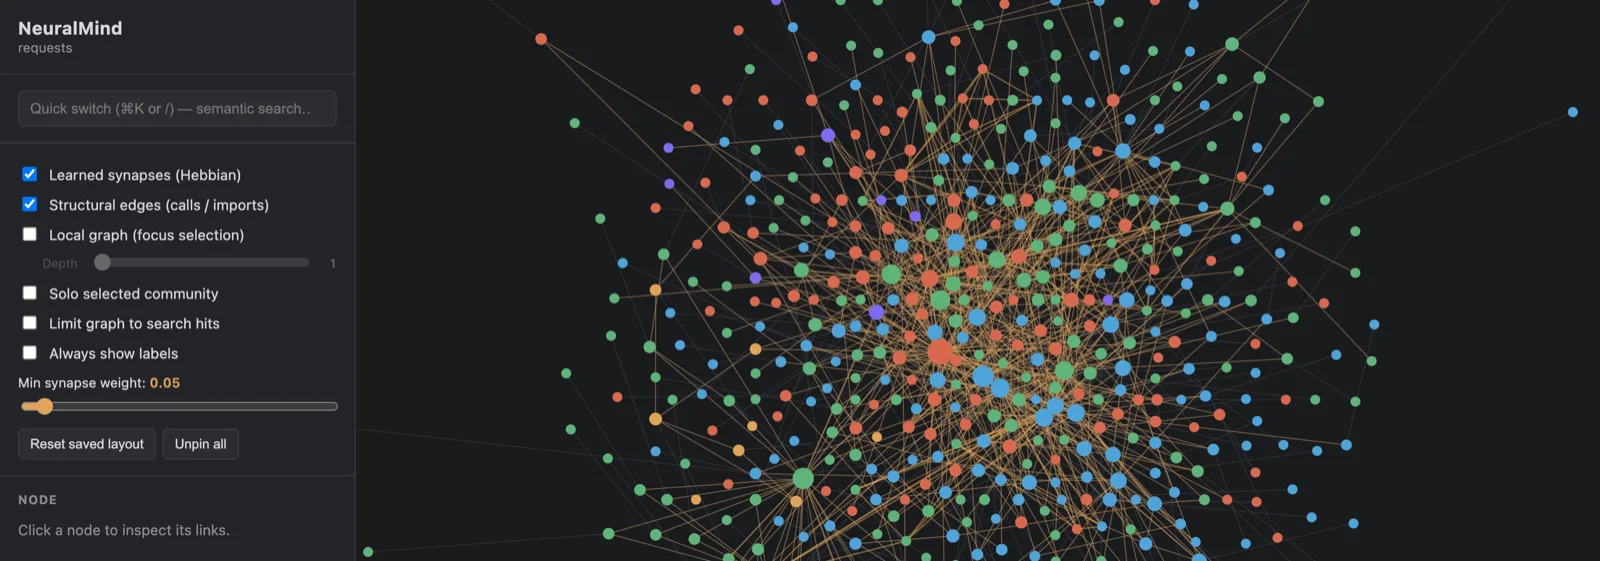
neuralmind serve: the psf/requests index with structural edges and learned synapses overlaid. Local, read-only, behind a per-session token.Measured, with the misses published
The public benchmark, per repo
Reproducible| Repo | Queries | NeuralMind tokens | ripgrep tokens | Every file | Found: NM / rg |
|---|---|---|---|---|---|
| requests | 14 | 816 | 26,543 | 41,729 | 100% / 71% |
| click | 7 | 670 | 45,059 | 78,514 | 100% / 71% |
| flask | 10 | 861 | 26,891 | 59,013 | 100% / 80% |
| rich | 9 | 961 | 43,437 | 232,483 | 100% / 100% |
Mean tokens per query (tiktoken o200k_base), from the committed run. Pre-registered queries on pinned commits; a gold file is the definition site of the symbol asked about, so there is no judge to argue with. All four backends, MRR and the reproduce command
Task outcomes: a 20-task pilot found no difference
PilotFewer tokens in the window isn’t the same as a lower cost per task. In a pre-registered pilot, Claude Code solved 18 of 20 bug-fix tasks without NeuralMind and 18 with it, at a median per-task cost change of +0.0% (95% CI −5.2% to +8.6%). The reason: in 60 runs the agent never called NeuralMind’s tools. The pilot, its spec and every run
- Token-reduction floor
4.0×
On the ~500-line CI fixture; the build fails below it. A floor, not the headline.
CI-gated- Learned recall
Never lowers hit rate
Synapse recall on vs off, at a neutral token budget, on the same fixture: it shows direction, not size.
CI-gated- Facts vs naive truncation
+0.265
At an equal token budget, measured with CI’s command on one machine at v4.12.0 (0.839 vs 0.574). CI fails below −0.10; v4.3.4 was a published loss.
CI-gated- Field report, one repo
48.8×
A ~9,300-node private TypeScript codebase, against the fixed 50K-token estimate the CLI used before v4.5.0. Method reproducible, not CI-gated.
Field report
Read the field report, before-and-after numbers included
How it compares
Each row says only what has been measured here. Where nothing has, it says that.
| Approach | What your agent gets | What’s measured here |
|---|---|---|
| NeuralMind | A project map, the relevant symbols and their callers, plus links learned from use. Rebuilt by git hooks; says when it is stale. | Public benchmark: the gold file on 40 of 40 queries. |
| Keyword search (ripgrep) | Files that contain the question’s words, opened whole. Always current. | Same benchmark, top five files opened whole: the gold file on 32 of 40, at more tokens on every repo. |
| Vector RAG | The chunks whose embeddings sit closest to the question. | Same benchmark, NeuralMind’s own index alone: cheaper on all four repos, and it ranks the gold file higher on flask and rich. NeuralMind’s recall is at or above it on every repo. |
| CLAUDE.md and rules files | What you wrote by hand, current until the code moves on. | Not benchmarked: a different job. They compose — CLAUDE.md can import the SYNAPSE_MEMORY.md NeuralMind exports. |
| Cursor and Windsurf memory | Memories and an index inside one editor’s agent. | Not benchmarked here. NeuralMind serves every MCP agent from one index in your repo. |
| codebase-memory-mcp | A structural graph from one static binary, across far more languages, indexed faster. | One retrieval head-to-head, June 2026 (NeuralMind v0.33.0), on requests and click only, not re-run since. |
The number that decides it is yours
Run neuralmind benchmark . for tokens per question on your code, and neuralmind eval . --synapse-ab with your own questions to see whether learned recall helps on your repo. How to measure your own
$ pip install neuralmind
$ cd your-repo && neuralmind build .
$ neuralmind benchmark .
Memory your team shares, evidence your client’s reviewer asks for
Team memory travels with git
neuralmind memory publishwrites the learned associations — weights, no source code — to a file you commit. Teammates’ agents import it on their next session.- Publishing follows the scope and weight threshold an admin sets, borderline imports wait in a review queue, and removing an association retracts it for everyone.
- Every publish, import, review and admin change lands in a hash-chained audit log you can verify and export.
NeuralMind Team, $29/user/mo, 5–50 seats, annual contract: seats beyond one, priority support and an annual invoice.
Local by default, verifiable per release
- By default, no telemetry and no repository content off your machine. One public model download on first build, pre-seedable for air-gapped installs.
- Signed images and build-provenance attestations you can verify with cosign and
gh attestation verify, a CycloneDX SBOM and an OpenVEX statement. security.profile: cui,neuralmind scan-for-secrets,neuralmind data-locationsand an SP 800-53 hardening check — evidence for your review; NeuralMind holds no certification.
Want it measured on your repos before a rollout?
The Codebase Fit Assessment benchmarks NeuralMind on one to three of your repos, on your hardware, and ends in a written keep-or-skip recommendation. Fixed fee, per organization.
Common questions
Who is NeuralMind for?
Anyone reviewing or changing code they didn’t write with a coding agent, and in particular small consultancies whose engineers rotate between client repositories. On day one in a stranger’s codebase the index and the prompt-time hook put the likely files in front of the agent; "neuralmind impact", "neuralmind review" and "neuralmind drift" turn a diff into a review the client can act on; "Decision:" trailers and "neuralmind why" leave the reasoning in the client’s history; and for a regulated client the signed releases, SBOM, CUI profile and SP 800-53 hardening check are the evidence their security review asks for. It runs on the engineer’s machine: by default no telemetry and no repository content leaves it. The walkthrough is docs.neuralmind.uk/use-cases/consultancy-client-code-review.html.
Does NeuralMind work with Claude Code, Cursor, Codex and other agents?
NeuralMind runs as a standard MCP server, so any MCP-compatible agent can use it. Claude Code is tested end to end and also gets lifecycle hooks — memory at session start, prompt-time recall and a stale-decision guard. Cursor, Cline, Continue and Codex connect through the same protocol; the MCP handshake is verified against Codex, but we have not driven those agents end to end in CI, so the README labels them theoretical. "neuralmind install-mcp" registers the server with Claude Code (add --client for Cursor, Cline, VS Code or Claude Desktop), and other clients point their MCP config at "neuralmind-mcp". There is also a CLI and a Python API.
How much does NeuralMind reduce Claude Code token usage?
It depends on your repo, so measure it. On the public benchmark — 40 pre-registered queries on requests, click, flask and rich — NeuralMind’s context was 51–242× smaller than pasting every source file, and it found the gold file on all 40. Pasting everything is the easiest baseline to beat: against ripgrep opening its top five files, closer to how an agent works, it was 31–67× smaller, and ripgrep found the gold file on 32 of 40. An agent that reads only the matching lines pays less still, and that is not measured. On private repos, "neuralmind benchmark ." reported 12–50× before v4.5.0, against a fixed 50K-token estimate; it now divides the measured size of your own code, so run it and read yours. That is what reaches the agent’s window, not what a task costs: a pre-registered 20-task pilot ran Claude Code with and without NeuralMind and found no difference in tasks solved or cost per task, because the agent never called NeuralMind’s tools (neuralmind.uk/benchmark/#task-outcomes). NeuralMind no longer claims savings on tool output: its old compression hooks, measured against how Claude Code actually handles hook output, added tokens instead of saving them, so they were switched off (docs.neuralmind.uk/benchmarks/compression.html).
How is this different from RAG or a vector database?
Plain RAG retrieves text chunks that look similar to the question. NeuralMind keeps a graph of your code — symbols, imports, call edges — assembles a structured context from it (project map, relevant symbols, their callers), and adds a synapse layer that learns which files you use together. On pure findability a vector index is a strong baseline: in the public benchmark, NeuralMind’s own index alone (top 8 entries, names and docstrings, no code) costs fewer tokens on every repo and still ranks the gold file higher on flask and rich, though NeuralMind’s recall is now at or above it everywhere — and we publish that. NeuralMind spends its extra tokens on context an agent can answer from, and on memory that persists between sessions.
Does NeuralMind get better the more I use it?
It is built to: the synapse layer strengthens links between files you use together and lets unused ones fade, and recall uses those links to re-rank results. What is shown so far is narrower. CI checks that learned recall never lowers the hit rate, on a ~500-line fixture, which shows direction rather than size. Nothing we publish yet shows it improving retrieval on a real codebase over weeks of use, and a 20-task pilot found agents solved the same tasks at the same cost with and without NeuralMind. You can measure the first on your own repo: write down questions with the file that answers each (past incidents, phrased as the symptom), then run "neuralmind eval . --synapse-ab" (v4.14.0+), which runs them with synapse recall on and off and records the difference each time.
What does NeuralMind remember, and what does it forget?
It remembers your code, which files you use together, the decisions recorded about the code and what your last session was doing. It keeps no profile of you or your preferences; those belong in CLAUDE.md or your agent’s own memory. What it learns from your work on a feature branch goes into that branch’s own namespace automatically (v0.24.0+), and since v4.22.0 the call graph each build finds, and the memory file Claude Code loads, follow the checkout too, so neither recall on the default branch nor that file sees a feature branch. The code index does not decay. Learned associations do, on a 30-day default half-life that each one adjusts between 3 and 120 days by how often it was used, and an association used five or more times keeps a floor. Every agent gets the same plain-text context, and Claude Code gets the most from it through its hooks. Each answer, with the code behind it: neuralmind.uk/what-it-remembers/.
How is NeuralMind different from CLAUDE.md or Cursor rules?
CLAUDE.md and rules files are instructions you write and maintain by hand. NeuralMind is memory the agent builds by working: a queryable index of the whole codebase plus associations learned from use. The two compose — NeuralMind exports its learned hub files and associations to SYNAPSE_MEMORY.md, which Claude Code loads at session start and your CLAUDE.md can import.
Does any of my code leave my machine?
By default, NeuralMind itself sends no telemetry and transmits no repository content off your machine — the graph, embeddings and synapse store live in your project directory. Its only default outbound request downloads a public embedding model on first build (again only if the cached copy is removed), and you can pre-seed it for air-gapped installs. One opt-in feature, off by default, sends README and architecture-doc prose to Anthropic under your own API key. What does leave is the context slice your agent sends to its own model provider, which NeuralMind makes smaller but does not control.
Is NeuralMind free? What does the paid tier buy?
The core is MIT open source, including everything that reduces tokens. A free 1-seat license auto-issues the first time you run "neuralmind wakeup ." — no signup, no expiry — and it unlocks every feature, including shared-memory governance, the hash-chained audit log and self-hosted deployment. NeuralMind Team ($29/user/mo, annual, 5–50 seats) buys seats beyond one, priority support and an annual invoice. You pay for seats and support, not for features.
How does team memory work?
Run "neuralmind memory publish" and the project’s learned associations are written to .neuralmind-team-memory.json at the repo root — learned weights, no source code. Commit that file, and every teammate’s agent imports it on the next session or build; each association is quality-scored on the way in, and borderline ones wait in a review queue. A new hire’s agent starts already knowing that the auth handlers go with the JWT utilities, instead of relearning it from scratch.
Where does NeuralMind lose?
Five places, all published. On real tasks, a pre-registered 20-task pilot found no difference: 18 of 20 solved with and without NeuralMind, at the same cost per task, and the agent never called NeuralMind’s tools. It finds all 40 public-benchmark queries, but 40 is a small sample: on a 150-question retrieval eval it misses the gold file in the top five on 10, most of them where vector search ranks that file outside the 20 candidates NeuralMind re-ranks. If all you need is to locate a file, a bare vector index is cheaper, and on flask and rich it still ranks the gold file higher. On the CI fixture it took until v4.12.0 to beat naive truncation at the same token budget (+0.265 at v4.12.0, 0.839 vs 0.574, measured on one machine; v4.3.4 was a loss, −0.054), CI gates only that it stays above −0.10, and that fixture is small. And the synapse layer needs real use to learn: a fresh install has no learned associations yet.
What languages does it support?
Ten out of the box via bundled tree-sitter grammars: Python, TypeScript (and JavaScript/JSX, parsed with the TypeScript grammars), Go, Rust, Java, C, C++, C#, Ruby and PHP — plus OpenAPI, SQL DDL and Protocol Buffers schema files. Markdown and text can be indexed too, as their own content project.
The right code, in fewer tokens. Measured in the open.
One command to install, one to index, one to measure it on your own repo. Every benchmark is published with its misses, and so is the task-outcome pilot that found no difference.
$pip install neuralmind- No telemetry
- Runs on your machine
- MIT core, free at 1 seat